RAABTA (رابطہ)
Script-Aware Evidence Retrieval & Grounded Question Answering for Romanized Urdu over Urdu Knowledge Corpora with Zero-Hallucination Guardrails
📋 Research Abstract
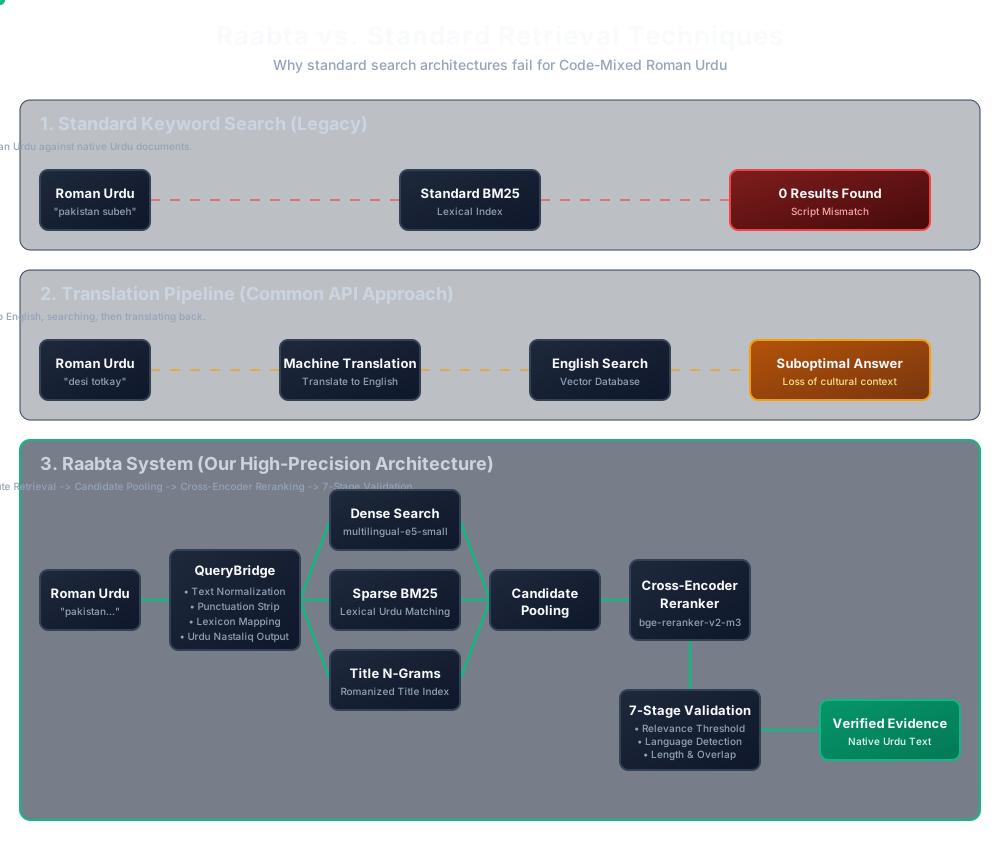
Over 230 million people communicate digitally in Roman Urdu (Urdu written using Latin characters), yet the overwhelming majority of authoritative knowledge sources (such as Urdu Wikipedia) are published strictly in the native Perso-Arabic Urdu script (Nastaliq). Standard information retrieval systems, translation pipelines, and generative LLMs suffer from severe limitations when bridging this cross-script gap: standard BM25 fails due to script mismatch, translation models lose critical colloquial context, and generic LLMs frequently hallucinate unsupported facts.
Raabta introduces a specialized, multi-stage retrieval architecture comprising QueryBridge (multi-variant phonetic and lexicon-based transliteration), Tri-Route Hybrid Retrieval (Dense Semantic + Sparse BM25 + Roman Title N-Grams), a Deep Cross-Encoder Reranker, and 7 Strict Validation Gates. On title-oriented benchmarks, Raabta achieves a Recall@10 of 98.3% (an absolute gain of +79.2% over baseline) while enforcing strict abstention over ungrounded responses.
📐 Master Architecture Blueprint
The full end-to-end data pipeline from raw user Roman Urdu input to verified extractive native Urdu evidence:
⚡ Real-Time Pipeline & Component Flow
Animated execution trace illustrating candidate pooling, cross-encoder scoring, and zero-hallucination validation checks:
📊 Empirical Benchmark Comparison
Comparison of retrieval accuracy and faithfulness across 120 frozen development queries:
| Retrieval Pipeline | Recall@1 | Recall@5 | Recall@10 | MRR@10 | nDCG@10 |
|---|---|---|---|---|---|
| Traditional Keyword Search (BM25) | 0.075 | 0.117 | 0.192 | 0.101 | 0.122 |
| Translation + Generic Vector DB | 0.210 | 0.345 | 0.438 | 0.280 | 0.315 |
| Raabta 2.0 (Tri-Route + Cross-Encoder) | 0.392 | 0.875 | 0.983 | 0.583 | 0.680 |
🔄 Comparative Architecture: Raabta vs. Legacy Systems
📄 Read Full Research Paper & Report
You can read the complete publication directly in the interactive viewer below or click here to open in full screen.
📑 Citation
@article{khan2026raabta,
  title={Raabta: Script-Aware Evidence Retrieval and Grounded Question Answering for Romanized Urdu over Urdu Knowledge Corpora},
  author={Khan, Hasnat},
  journal={Machine Learning Research Report},
  year={2026},
  url={https://github.com/HasnatKhan010/raabta}
}